Department series
Drive
Interactive evals and field studies — evidence, not marketing.
Crosstalk
How agents talk — to each other, to your tools, and to the world outside the box. The humans move up a level.
- Token costs reversed their multi-year decline mid-2026 — +29% intelligence-adjusted, +76% raw. If it holds, efficiency stops being optional and the token budget becomes a first-class design constraint. — The World's Fair Report · Jul 15
- Boring file architectures won retrieval: memory systems shipping with no vector database at all, embeddings reframed as cached compute, grep as the baseline. — The World's Fair Report · Jul 15
- The phone-only project now has a front door: Grok Bot signs in with your Cursor account and hands repo work to a Cursor Cloud Agent, so the switchboard is something you text rather than wire. It only works if the environment was set up on Cursor first. — Never Touch the Laptop · Sep 3
- Jev is a classifier interface inside the model: you ask a fixed menu of judgments instead of continuing, completing, or calling tools. DeepSeek can return the same typed answers; speed and constraints are the difference — Jev’s p50 was 400 ms against 2,377 ms, and one wrong answer still came back at 0.98. — Jev: Judging, Not Calling Tools · Sep 20
-
Jev: Judging, Not Calling Tools
A new LLM interface: instead of a continuation, a tool call, or a free-form completion, you ask a fixed set of judgments — a high-speed classifier. Umwelten’s types, a claim-and-passage walkthrough, and a Jev vs DeepSeek pilot.
-
Never Touch the Laptop: Running a Whole Project from Your Phone
Grok Bot dispatching to Cursor Cloud Agents, Cursor environment setup, Amp orbs, Codex Cloud, and Claude Code on the web mapped across 13 axes — voice, secrets, MCP, previews, and the build loop — against the idealized phone-only project.
-
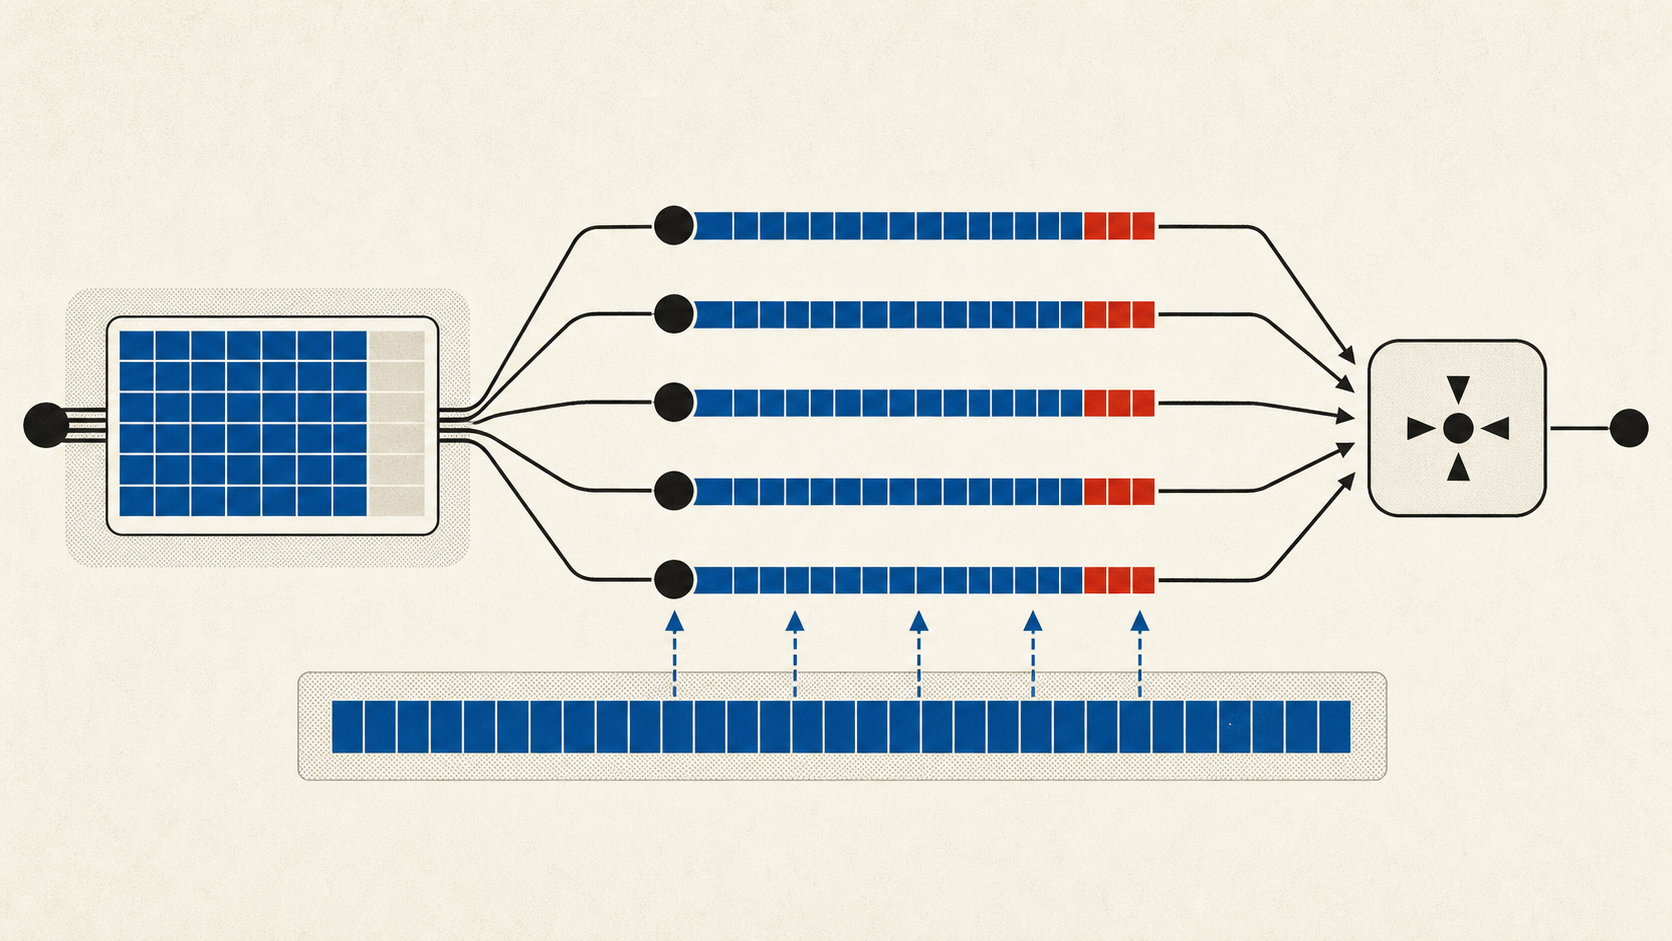
Conversation Roots, KV Reuse, and Local Agent Throughput
How to win local KV reuse: exact prefix rules, slot sizing, and measured results across Ollama and llama.cpp on a 64 GB M4 Max—same mechanism, one study.
-

AI Engineer World's Fair 2026 — The Complete Talk Roundup
Every talk from the fair, read and distilled — 92 write-ups from ~319K words of transcripts, nine topic tracks, and the cross-cutting surprises.
Dispatches
Filed from the floor — the patterns unfreeze in Miami, and the Linux moment arrives on the laptop.
Proofs
Show your work — 131 models, honest margins, and the thesis that it's agents all the way down.
-

Testing 48 LLMs Across 5 Dimensions for $4.63
Interactive leaderboard across reasoning, knowledge, instruction following, coding, and MCP tool use.
-

Can LLMs Use Real-World Tools?
39 models, real Rivian driving data via MCP — most can call tools; fewer call the right ones.
-

The Car Wash Test: Do LLMs Have Common Sense?
131 models, one question — should you walk or drive to the car wash?
Instruments
Reading the gauges — before you trust an agent, you need instruments that show you when it's lying.
Field Trials
Take the tools outside and see what breaks — agents become products, and products can be raced.