Drive
Interactive evals and field studies — evidence, not marketing.
-
Jev: Judging, Not Calling Tools
A new LLM interface: instead of a continuation, a tool call, or a free-form completion, you ask a fixed set of judgments — a high-speed classifier. Umwelten’s types, a claim-and-passage walkthrough, and a Jev vs DeepSeek pilot.
-
Never Touch the Laptop: Running a Whole Project from Your Phone
Grok Bot dispatching to Cursor Cloud Agents, Cursor environment setup, Amp orbs, Codex Cloud, and Claude Code on the web mapped across 13 axes — voice, secrets, MCP, previews, and the build loop — against the idealized phone-only project.
-
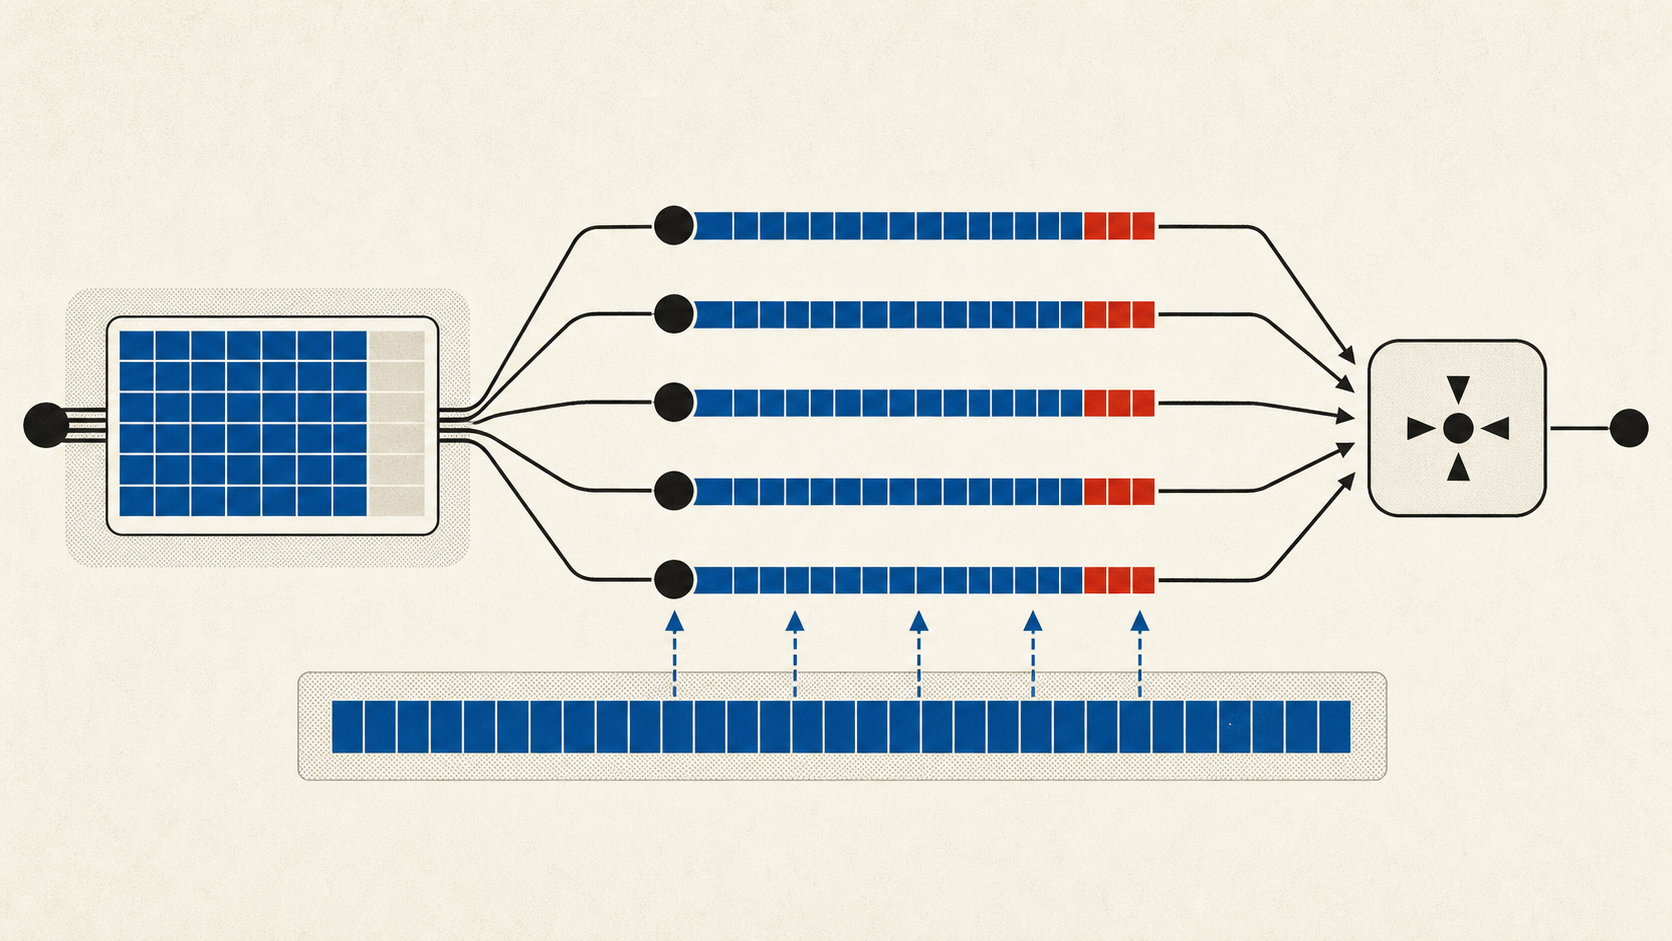
Conversation Roots, KV Reuse, and Local Agent Throughput
How to win local KV reuse: exact prefix rules, slot sizing, and measured results across Ollama and llama.cpp on a 64 GB M4 Max—same mechanism, one study.
-

AI Engineer World's Fair 2026 — The Complete Talk Roundup
Every talk from the fair, read and distilled — 92 write-ups from ~319K words of transcripts, nine topic tracks, and the cross-cutting surprises.